Setting Up Thrift Server for Yeedu
Overview
This guide provides instructions for configuring a Yeedu Thrift Server to interact with a JDBC client. The Thrift Server enables executing SQL queries using various client applications, such as BI tools and SQL editors.
Prerequisites
- Operates exclusively in YEEDU mode of a cluster.
- Supported Spark versions: 3.5.3 and 3.4.3. A runtime version supports Thrift only if it carries the Thrift Support badge in the cluster's Run Time Version dropdown.
- Requires cluster association with a workspace.
- Permissions required: CAN RUN, CAN EDIT, or CAN MANAGE on the workspace.
Configuration Steps
Access the JDBC Section
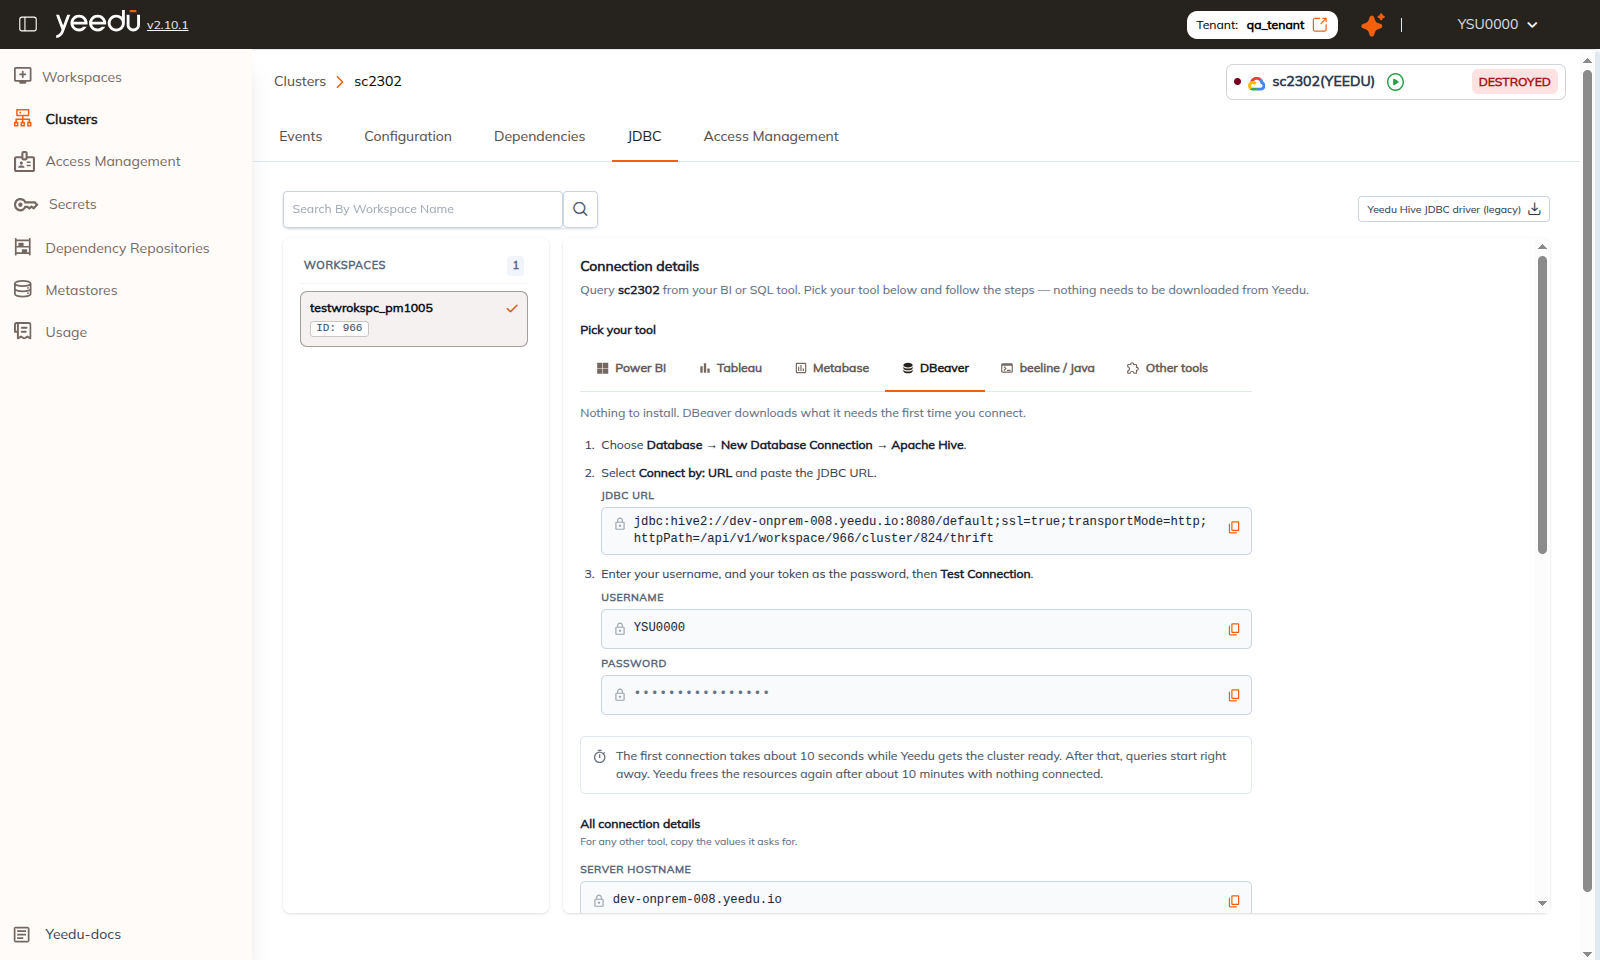
The JDBC section provides pre-configured connection parameters, connection strings, and step-by-step guides for popular BI and SQL tools (including Power BI, Tableau, Metabase, DBeaver, and beeline). You can access it either from the Clusters Dashboard or from the Workspaces Dashboard.
From Clusters Dashboard
- Open the Clusters Dashboard in the Yeedu UI.
- Select a cluster from the list and open the JDBC tab.
- The page presents:
- Workspaces list (left pane): Select the workspace through which you want to query the cluster.
- Pick your tool (main pane): Dedicated setup tabs for Power BI, Tableau, Metabase, DBeaver, beeline / Java, and Other tools.
- All connection details: Copyable cards for SERVER HOSTNAME, PORT, HTTP PATH, TRANSPORT MODE, SSL, USERNAME, PASSWORD / TOKEN, SERVER URL, and JDBC URL.
- Yeedu Hive JDBC driver (legacy): Download button (top-right) if your environment requires the standalone JAR.
From Workspaces Dashboard
- Open the Workspaces Dashboard in the Yeedu UI.
- Select a workspace from the list and open the JDBC tab.
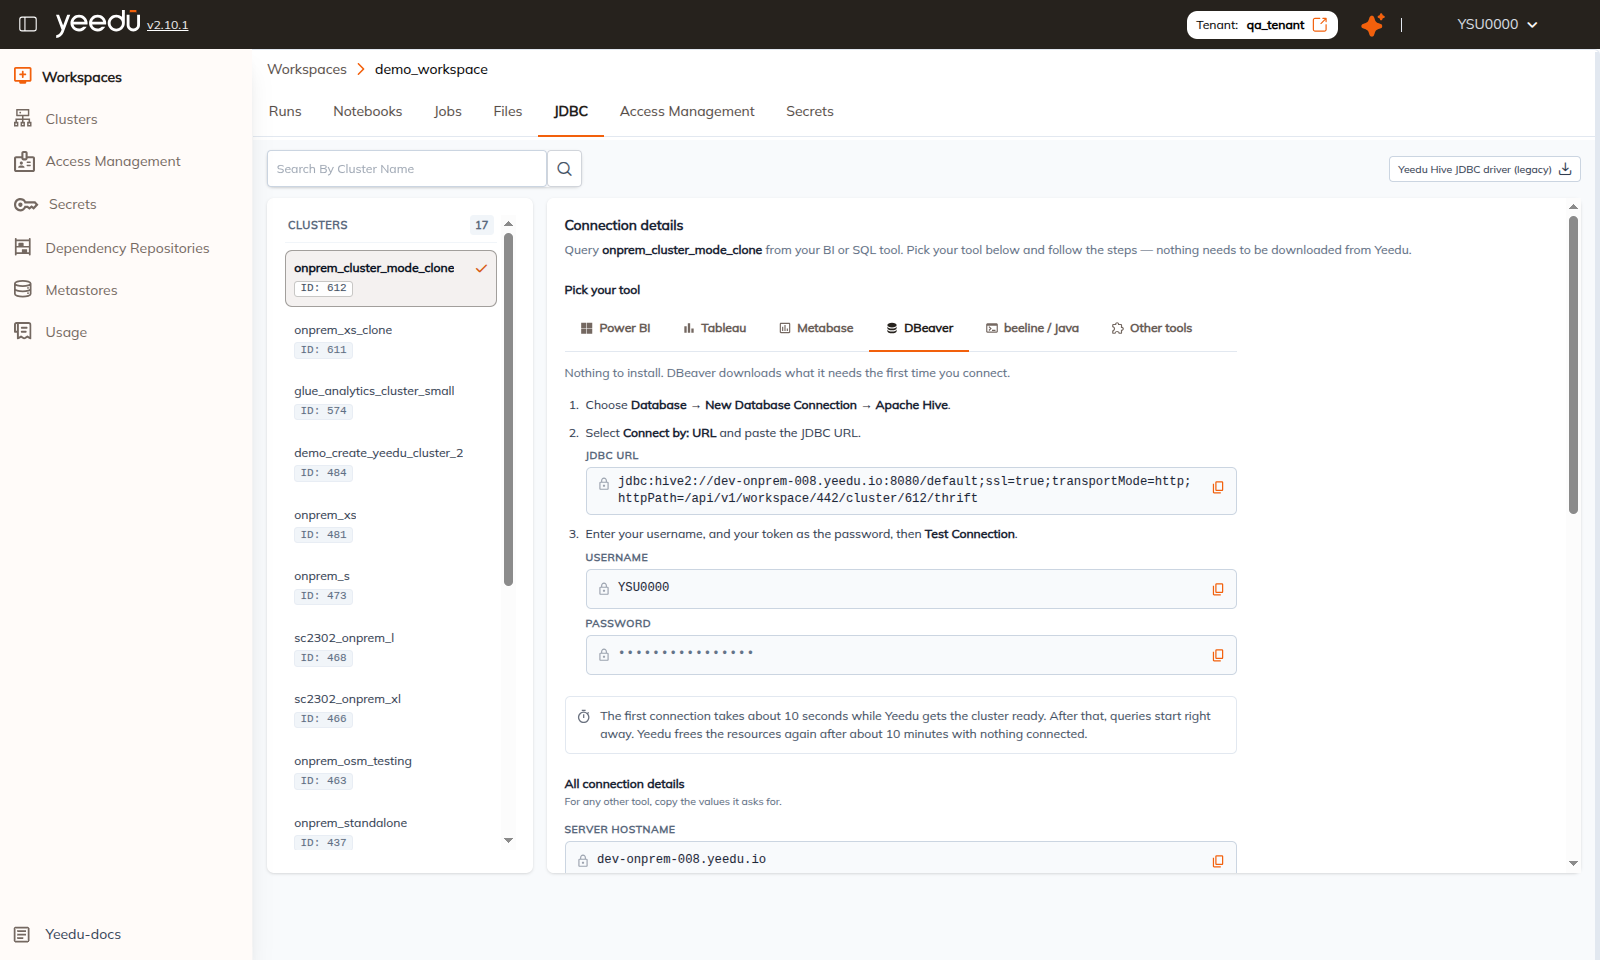
- The page presents:
- Clusters list (left pane): Select the cluster you want to query.
- Pick your tool (main pane): Interactive setup guides pre-filled for each client tool.
- All connection details: Complete list of individual host, port, path, and security parameters.
- Yeedu Hive JDBC driver (legacy): Download link for legacy client applications.
Connecting with DBeaver
In Yeedu v2.10.1, you can connect directly using DBeaver's built-in Apache Hive driver without manually installing or configuring external JAR files.
Recommended: Built-in Apache Hive Driver
- Open DBeaver and click New Database Connection (or Database → New Database Connection).
- Choose Apache Hive from the list of database drivers and click Next. (DBeaver will automatically download the standard driver if needed).
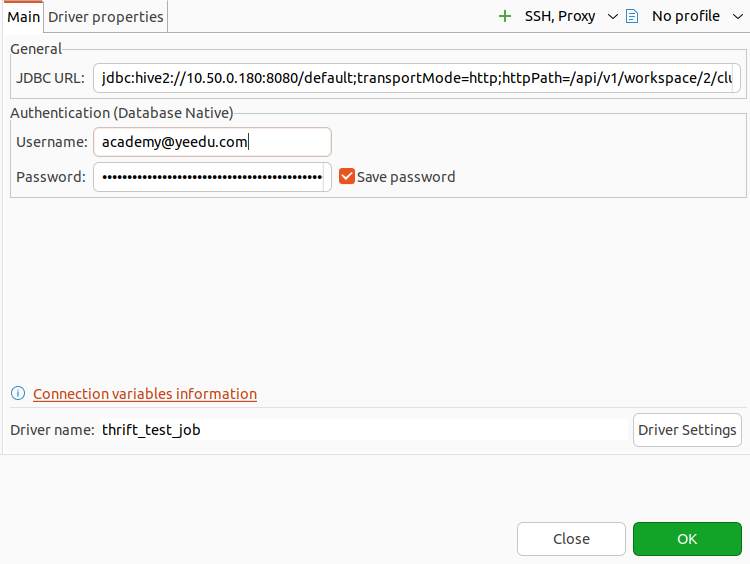
- Under General, select Connect by: URL.
- Copy the JDBC URL from the Yeedu JDBC tab and paste it into the JDBC URL field. Example:
jdbc:hive2://dev-onprem-008.yeedu.io:8080/default;ssl=true;transportMode=http;httpPath=/api/v1/workspace/442/cluster/612/thrift
- In the Authentication section:
- Username: Enter your Yeedu username (e.g.
YSU0000). - Password: Paste your Yeedu session token from the PASSWORD / TOKEN field.
- Username: Enter your Yeedu username (e.g.
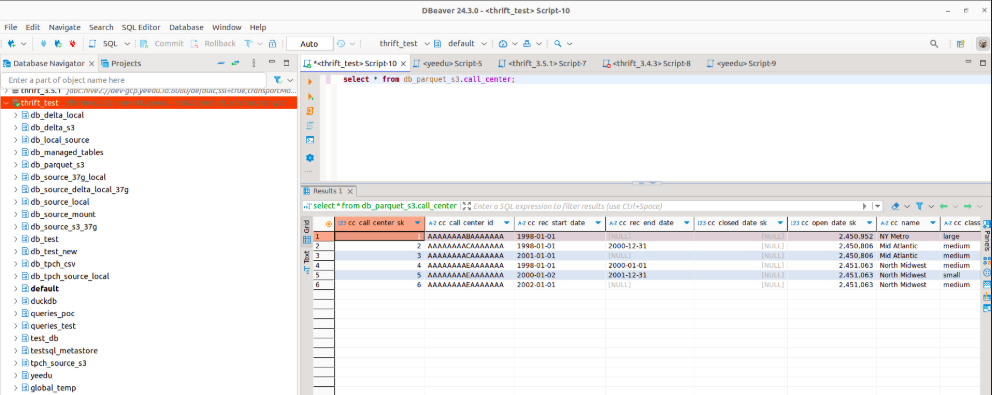
- Click Test Connection. Once verified, click Finish.
- Open a SQL editor in DBeaver and begin running queries against your cluster.
Alternative: Using the Custom Yeedu Legacy Driver
If your environment or corporate policy requires using Yeedu's dedicated standalone JAR:
- Click Yeedu Hive JDBC driver (legacy) in the top right of the Yeedu JDBC tab to download
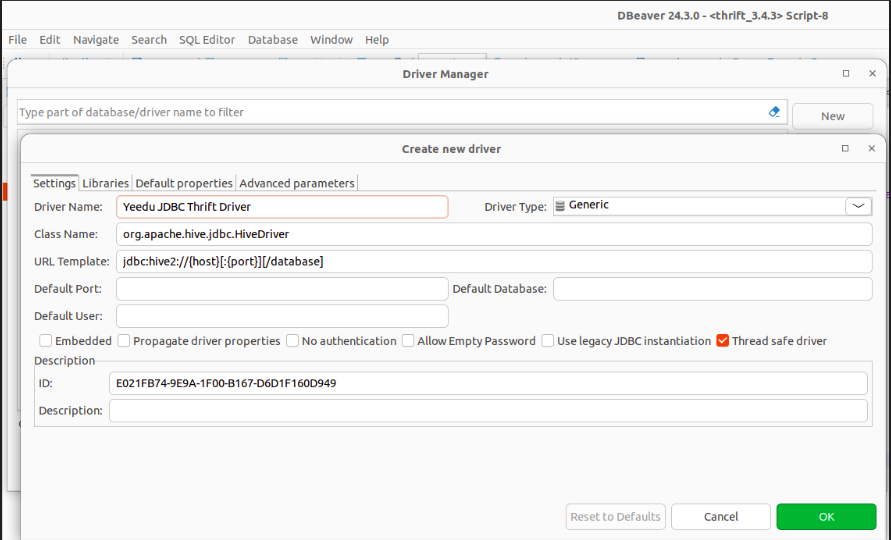
hive-jdbc-3.1.3-standalone.jar. - In DBeaver, navigate to Database → Driver Manager and click New.
- Complete the Settings tab:
- Driver Name:
Yeedu JDBC Thrift Driver - Class Name:
org.apache.hive.jdbc.HiveDriver - URL Template:
jdbc:hive2://{host}[:{port}][/database]
- Driver Name:
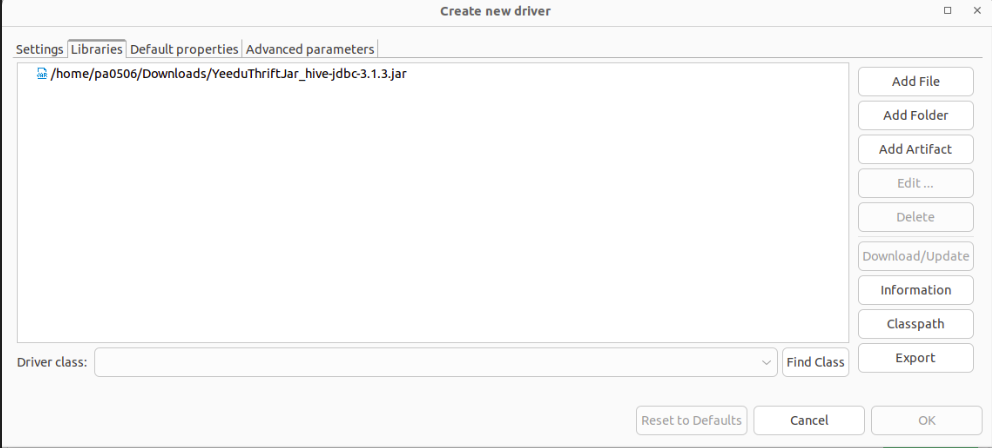
- In the Libraries tab, click Add File and select the downloaded JAR file.
- Create a new database connection selecting the configured driver and paste the JDBC URL and credentials.
Connection Options
1. Unencrypted Connection
Use the following JDBC URL for an unencrypted connection:
jdbc:hive2://{hostname}:{port}/default;transportMode=http;httpPath=/api/v1/workspace/{workspace_id}/cluster/{cluster_id}/thrift;maxJobStartTimeout=5;
- maxJobStartTimeout: How long, in minutes, the driver waits for the Thrift server job to reach a running state before giving up (default:
5). If the server does not start in time the driver fails with "Failed to start the Thrift server within the allotted time of N minutes".
2. SSL-Enabled Connection
For secure connections, include ssl=true and specify the truststore:
jdbc:hive2://{hostname}:{port}/default;ssl=true;sslTrustStore=<trust_store_path>;trustStorePassword=<trust_store_password>;transportMode=http;httpPath=/api/v1/workspace/{workspace_id}/cluster/{cluster_id}/thrift;ignoreHttpVerify=false;maxJobStartTimeout=5;
- sslTrustStore=
<trust_store_path>: Specifies the location of the client's truststore file. - trustStorePassword=
<trust_store_password>: The password required to access the truststore.
3. SSL with ignoreHttpVerify=true
Bypass truststore validation using the following JDBC URL:
jdbc:hive2://{hostname}:{port}/default;ssl=true;transportMode=http;httpPath=/api/v1/workspace/{workspace_id}/cluster/{cluster_id}/thrift;ignoreHttpVerify=true;maxJobStartTimeout=5;
- Parameters sslTrustStore and trustStorePassword are not required in this configuration.
The property name is case-sensitive: ignoreHttpVerify, not ignoreHTTPVerify. A misspelled key is
ignored silently and the driver falls back to the default (false), i.e. full certificate verification.
JDBC URL parameter reference
Every parameter below is a session variable — it goes after the database name, separated by ;.
| Parameter | Default | Meaning |
|---|---|---|
transportMode | — | Must be http for Yeedu. |
httpPath | — | /api/v1/workspace/{workspace_id}/cluster/{cluster_id}/thrift — identifies the workspace and cluster the Thrift server runs on. |
ssl | false | Set to true to connect over HTTPS. |
sslTrustStore / trustStorePassword | — | Client truststore and its password. Required when ssl=true and ignoreHttpVerify=false. |
ignoreHttpVerify | false | When true, skips certificate verification, so no truststore is needed. Case-sensitive. |
maxJobStartTimeout | 5 | Minutes to wait for the Thrift server job to start. |
reuseSameConn | true | When true, a second connection opened with the same JDBC URL attaches to the Thrift server already started by the first one instead of launching another job run. Set it to false to force a dedicated Thrift server (and therefore a separate job run) per connection. |
The URL that Yeedu generates for you on the cluster page already includes these — for example:
jdbc:hive2://demo.yeedu.io:8080/default;ssl=true;transportMode=http;httpPath=/api/v1/workspace/{workspace_id}/cluster/{cluster_id}/thrift;reuseSameConn=true;ignoreHttpVerify=true;maxJobStartTimeout=5;